Built to order
EMARQUE AI HGX Rubin
- HBM4 GPU memory
- 2 TB
- Rubin GPUs
- 8
- NVFP4 inference, sparse
- 400 PF
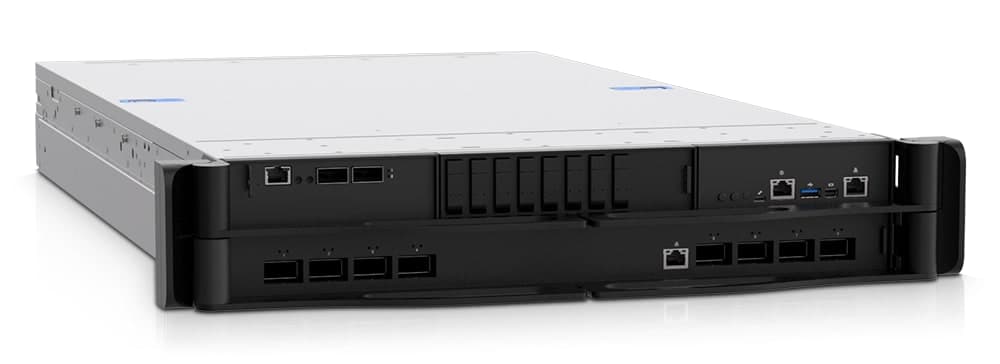
The price depends on the processors, memory, storage and networking specified around the eight-GPU board.
Key features
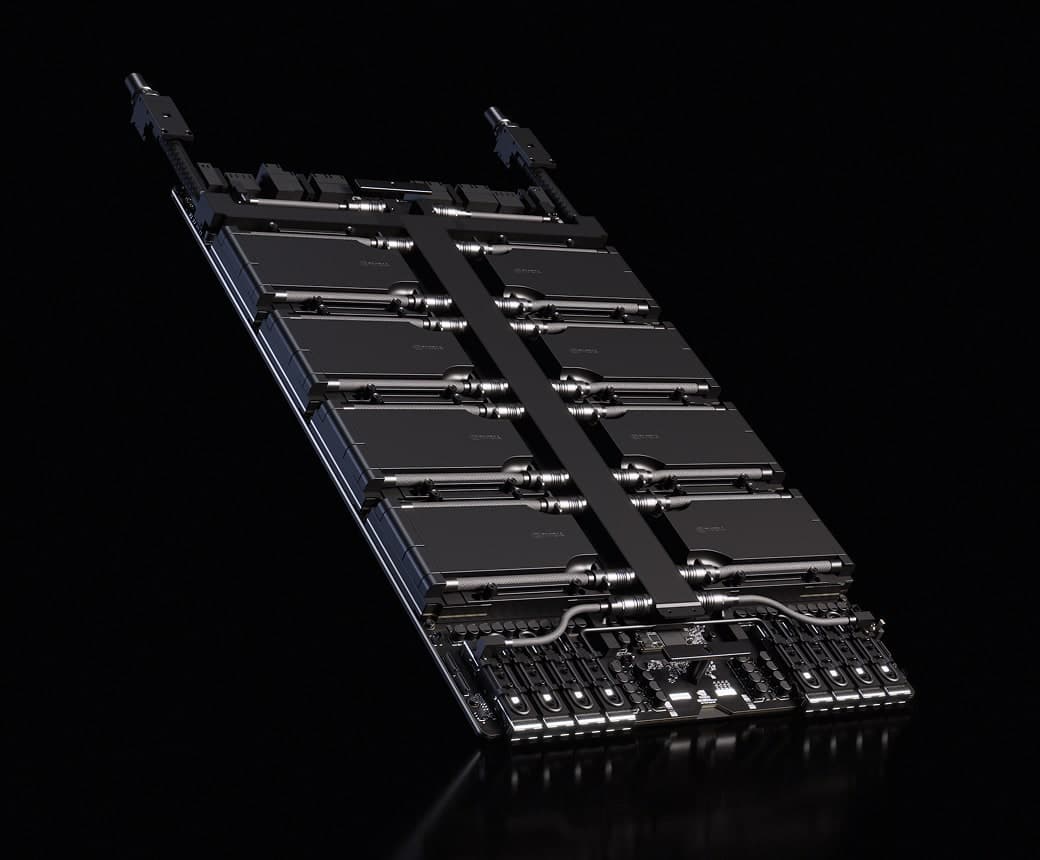
Eight Rubin GPUs working as one
Liquid-cooled from the start
The server is liquid-cooled by design. Eight GPUs of this class under sustained load put out more heat than most server rooms can move with air, and designing the cooling in avoids a retrofit.
Configured with you
Processors, memory, storage and networking are specified around your workload, as on every machine we build.
Sourced and set up by us
We source the platform through NVIDIA's OEM partners and coordinate the install with you. The warranty and support stay with us in Malaysia.
Use cases
- Training
Training on the Rubin generation
Teams that want NVIDIA's newest GPU generation for training and fine-tuning large models.
- Inference
Serving large models
Production serving where the cost of each rack unit and each watt decides whether the platform works at scale.
- Facilities
Liquid-cooled rooms
Sites already moving to liquid cooling, where air-cooled density has reached its limit.
Specifications
The final parts list is confirmed in your quote.
- GPU
- NVIDIA HGX Rubin NVL8: 8 × Rubin GPUs
- GPU memory
- 2 TB HBM4, 130 TB/s (NVIDIA figure)
- GPU interconnect
- Sixth-generation NVLink, 3.6 TB/s per GPU (NVIDIA figure)
- AI compute
- 400 PFLOPS NVFP4 inference with sparsity, 270 PFLOPS NVFP4 training dense (NVIDIA figures)
- Cooling
- Liquid cooling, designed in rather than retrofitted
- CPU and memory
- Dual AMD EPYC or Intel Xeon, chosen in your quote
- Storage
- Confirmed in your quote
Questions about the AI HGX Rubin
Can we order it?
Yes. It is built to order: tell us what it will run and who will use it, and we confirm the configuration in a written quote.AI HGX Rubin or AI HGX B300?
Both are eight-GPU servers built to order. The AI HGX Rubin is NVIDIA's newer generation and is liquid-cooled, so it needs a room with coolant distribution. The AI HGX B300 runs air-cooled in a standard server room. We help you choose on your models, your room and your budget.Why liquid cooling?
Eight GPUs of this class under sustained load put out more heat than air can remove in most server rooms. Specifying liquid cooling at the start keeps the GPUs off their thermal limits and avoids rebuilding the room later.What support does it come with?
The same as every machine we build: our system warranty, the component makers' warranties on top, and support from us in Malaysia.
Get a quote for the AI HGX Rubin.
Tell us what it needs to run and who will use it. We reply with a written quote in MYR.