Skip to content
EMARQUE AI
  1. Home
  2. Products
  3. AI PRO 500
Rackmount AI Server · Built to order in Malaysia

The 4-GPU rackmount AI server:
workstation-grade silicon.

AMD Threadripper PRO 9995WX. Up to 4 NVIDIA RTX PRO 6000 Blackwell GPUs. ECC end to end. Noctua air cooling in a SilverStone RM52 5U chassis. Picked, assembled, QA-tested, and supported by EMARQUE specialists in Klang Valley. Never re-badged OEM, never generic.

NVIDIA-PoweredAMD PartnerMulti-Point QAFrom RM 35,000
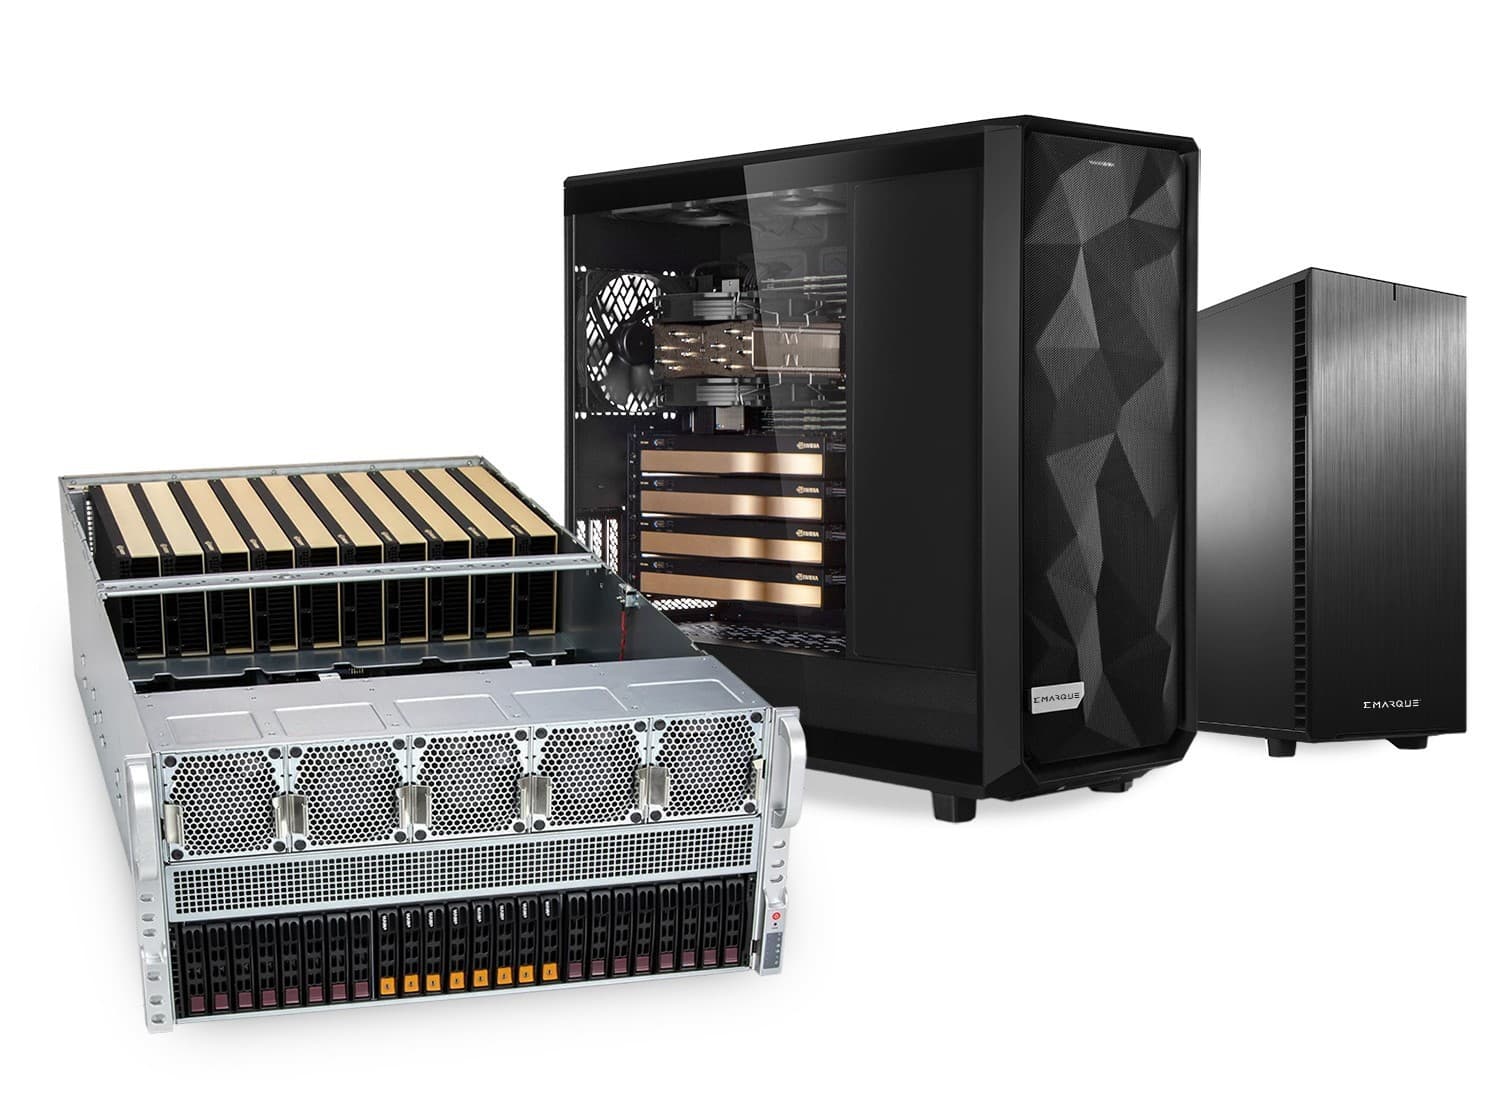
AI PRO 500: custom-built 5U rackmount AI server with AMD Threadripper PRO and up to 4 NVIDIA RTX PRO 6000 Blackwell GPUs, assembled in Malaysia
4GPUs in a 5U rackmountUp to four datacenter-class accelerators with airflow tuned for sustained AI loads in a SilverStone RM52 5U chassis.
256 GBECC DDR5-6400 memory8-channel WRX90 platform. Room for long contexts, embedding stores, and dataset shards in RAM.
30 TBGen5 NVMe primary storageU.2 NVMe pool with RAID. Sustained reads where it counts: model loading and inference cache.
Why AI PRO 500

A rackmount AI server specified for your workload, not a shelf SKU.

Every PRO 500 is built one at a time. EMARQUE chooses the chassis, motherboard, CPU SKU, GPU mix, cooling topology, and storage tier for the model size and concurrency you're actually serving.

Built to order in Malaysia

No re-badged OEM. EMARQUE picks the chassis, board, CPU, GPU mix, cooling, and storage for your workload, then assembles and validates it at the EMARQUE Lab in Klang Valley.
AMD Threadripper PRO foundation

Up to 96 cores, 192 PCIe Gen5 lanes, 8-channel ECC memory. Enough headroom for 4 GPUs and high-bandwidth NVMe pools without lane sharing.

Configurable GPU mix

NVIDIA RTX PRO 6000 Blackwell (96 GB GDDR7 ECC) or RTX 5090 (32 GB GDDR7). Pick the VRAM and FP precision your model actually needs.

Noctua air cooling

Noctua tower coolers on the CPU, ducted airflow across the GPU stack, low-noise case fans. Sustains peak clocks under multi-hour training without thermal throttle.

ECC end to end

Registered ECC DDR5 memory + ECC GDDR7 on RTX PRO 6000 Blackwell. Silent data corruption is not a debugging tax you should be paying in 2026.

Local multi-point QA

Every PRO 500 ships with multi-point QA across CPU, GPU, memory, and disk, plus a benchmark report run on a model class similar to yours.

Build options

Pick your parts. EMARQUE validates the combination.

Every option below is a real, current-generation component the EMARQUE Lab builds with. Not every combination is sensible. When a configuration is submitted EMARQUE sanity-checks it against thermal, power, and PCIe-lane budgets before quoting.

Open the configurator

CPU

Pick one
  • AMD Ryzen Threadripper PRO 9995WX: 96-core / 192-thread, 384 MB L3, 350 W TDP
  • AMD Ryzen Threadripper PRO 9985WX: 64-core / 128-thread
  • AMD Ryzen Threadripper PRO 9975WX: 32-core / 64-thread
  • AMD Ryzen Threadripper PRO 9965WX: 24-core / 48-thread
  • Alternative: Intel Xeon W9-3475X (36-core) or W7-3565X (32-core)

Motherboard

Pick one
  • ASUS Pro WS WRX90E-SAGE SE: 7 × PCIe Gen5, 8-channel ECC
  • ASRock Rack WRX90 WS EVO: workstation-grade, full BMC
  • Supermicro M12SWA-TF: for WRX80 Threadripper PRO 5000 builds

GPU (up to 4)

Pick any
  • NVIDIA RTX PRO 6000 Blackwell Workstation Edition: 96 GB GDDR7 ECC, 600 W
  • NVIDIA RTX PRO 6000 Blackwell Max-Q Workstation Edition: 96 GB GDDR7 ECC, 300 W (blower, multi-GPU stack)
  • NVIDIA RTX 5090: 32 GB GDDR7, 575 W (blower-style for 2-4 stack)

Memory

Pick one
  • 256 GB ECC DDR5-6400 RDIMM (8 × 32 GB)
  • 512 GB ECC DDR5-6400 RDIMM (8 × 64 GB)
  • 1 TB ECC DDR5-5600 RDIMM (8 × 128 GB; speed drops to 5600 with full population)

Primary storage

Pick one
  • 2 × 4 TB Samsung 9100 PRO M.2 NVMe Gen5: RAID 1 for the OS + workspace
  • Up to 4 × 7.68 TB Solidigm D7-PS1010 U.2 NVMe Gen5: RAID 10 for datasets
  • Up to 30 TB total Gen5 NVMe across M.2 + U.2 bays

Bulk storage (optional)

Pick any
  • Up to 8 × 24 TB Seagate Exos X24 (SAS / SATA): RAID Z2 for archive
  • Up to 200 TB raw with hot-swap bays
  • Optional: ZFS or BeeGFS for shared filesystem

Power supply

Pick one
  • Corsair AX1600i: 1600 W, 80+ Titanium, digital telemetry
  • Seasonic Prime TX-1300: 1300 W, 80+ Titanium
  • be quiet! Dark Power Pro 13: 1300 / 1600 W, 80+ Titanium

Cooling

Pick one
  • Noctua air: NH-U14S TR5-SP6 + Noctua low-noise case fans (default for the 5U chassis)
  • High-airflow air: redundant Noctua fans with ducted GPU airflow for 4-GPU configs
  • Optional liquid CPU loop: D5 pump, 360 mm radiator, EKWB or Bykski block on request

Chassis

Pick one
  • SilverStone RM52: 5U rackmount, high-airflow bays, standard for the AI PRO 500
  • Phanteks Enthoo Pro 2 Server Edition: for full 4-GPU + bulk-storage builds
  • Fractal Design Define 7 XL: sound-dampened pedestal option when a rack isn't available

OS

Pick one
  • Ubuntu 24.04 LTS Desktop or Server: default for AI workloads
  • Windows 11 Pro for Workstations: when your toolchain requires it
  • RHEL 9 / Rocky Linux 9: enterprise-supported environments
  • Custom image on request: supplied by your IT team

Component selections are validated before quotation. SKU availability and final pricing depend on the NVIDIA / AMD channel at order time. Every configuration is quoted in MYR.

Next step

Tell us your workload. EMARQUE sizes the PRO 500 and sends a quote.

Is this for you?

Client guidance: PRO 500.

How EMARQUE scopes this system: who it suits, when to pick it, when to pick something else, and what we add beyond the hardware.

Who it's for

Departmental AI owners: IT, data, or research team leads who need a quiet multi-GPU pedestal that serves a department without going to a server room.

Choose this when

  • 25–100 concurrent users on a private RAG, chat, or vision workload.
  • Fine-tuning 7B–70B class models with LoRA / QLoRA on your own data.
  • Office colocation: no dedicated server-room budget, but you still need ECC, redundant cooling, and steady-state inference.

Pick something else when

  • You're serving > 200 concurrent users or > 100B-class models in production. That's AI Server territory.
  • You need single-tenant air-gapped rackmount with redundant PSUs and hot-swap drives.
  • Multi-node training is on the roadmap. Go straight to AI Server or DGX-class.

Best-fit workloads

  • Departmental private RAG with 25-100 concurrent users
  • Production vision and voice pipelines with sub-second latency
  • Fine-tuning 7B-70B models with LoRA / QLoRA
  • Rack-ready departmental AI: 5U in a standard 19-inch rack

Model & memory fit

4 × RTX PRO 6000 Blackwell gives 384 GB of GPU memory across the four cards (no NVLink on this generation of RTX). Ideal for 30–70B inference and LoRA fine-tuning; for 70B+ full fine-tunes step up to AI Server with H200 NVLink.

Deployment shape

Pedestal tower, ~1.6–2 kW under load, sub-58 dBA at sustained load. Standard 240 V wall outlet; 10 GbE / 25 GbE optional uplink.

Alongside the rest of the lineup

Slots between DGX Spark (single-superchip, ≤ 70B quantized) and AI Server-class systems (rackmount, NVLink). Cheaper than DGX Station and configurable on a per-GPU basis. You choose RTX PRO 6000 Blackwell, RTX 5090, or a mix.

Upgrade path

When you outgrow 4 GPUs or need NVLink between GPUs, move to one of the EMARQUE AI Server configurations (RTX PRO 6000 SE, HGX B200, or HGX B300).

What EMARQUE adds beyond the hardware

  • Custom GPU mix: pick from RTX PRO 6000 Blackwell or RTX 5090.
  • Multi-point QA before delivery.
  • Quiet-air cooling tuning so you can actually put it in the office.
  • Pre-installed runtime (vLLM, Ollama, TGI) validated on your real workload.
Use cases

What the AI PRO 500 runs day to day.

Individual / small team

Solo researcher and small-team fine-tuning

LoRA / QLoRA fine-tunes on 7B–70B open-weight models. Iterate on prompts, evaluations, and quantization without queuing for a shared GPU.

Departmental

Departmental private RAG and agents

Serve 25–100 concurrent users on a single rig. Permission-aware retrieval over Slack archives, ticket queues, code repos, and document libraries.

Pre-production

Pre-production validation

Test pipelines, evaluate runtimes (vLLM, TGI, Ollama), and pin a working stack before scaling to the AI Server or DGX Station for org-wide rollout.

Vision / Voice

Real-time vision and voice prototyping

OCR, segmentation, multi-camera object detection, ASR, TTS. Rack-mounted in a lab or server room, driving build-and-test cycles.

Spec sheet

What's inside an AI PRO 500.

GPU
Up to 4 × NVIDIA RTX PRO 6000 Blackwell Workstation Edition · 96 GB GDDR7 ECC (384 GB total)
AI compute
4 PFLOPS FP4 per GPU · 16 PFLOPS aggregate
CPU
AMD Ryzen Threadripper PRO 9995WX, 96 cores / 192 threads (Zen 5)
Motherboard
ASUS Pro WS WRX90E-SAGE SE (WRX90, sTR5): 7 × PCIe 5.0 ×16, 8-channel DDR5
Memory
256 GB DDR5-6400 ECC RDIMM (expandable, 8-channel)
Storage
Samsung 9100 PRO 4 TB PCIe Gen5 NVMe (expandable)
Form factor
SilverStone RM52 5U rackmount, 19-inch standard rack
Power
3000 W PSU (Corsair)
Cooling
Noctua NH-U14S TR5-SP6 air cooling
OS
Ubuntu 24.04 LTS, RHEL 9, or Windows 11 Pro for Workstations

Configurations from RM 35,000 (single-GPU base) to RM 110,000+ depending on selection. Pricing in MYR.

FAQ

The AI PRO 500 in Malaysia: common questions.

  • What is the price of the AI PRO 500 AI server in Malaysia?
    AI PRO 500 starts at RM 35,000 (single-GPU base configuration) and scales to RM 110,000+ depending on CPU SKU, GPU count, GPU model, RAM, storage, and cooling choice. The configurator at /quote returns a live estimate; final pricing is confirmed by formal quotation.
  • Which CPU and GPU combinations does EMARQUE recommend for fine-tuning?
    For LoRA / QLoRA fine-tuning on 7B–34B models: Threadripper PRO 9975WX (32-core) + 2 × NVIDIA RTX 5090 (32 GB) is the sweet spot for cost-per-token. For 70B-class fine-tuning: Threadripper PRO 9985WX + 2 × NVIDIA RTX PRO 6000 Blackwell (96 GB) keeps the model in VRAM without offload. EMARQUE confirms the exact recipe at quotation against the real workload.
  • Can the AI PRO 500 be rack-mounted?
    Yes. The standard chassis is the SilverStone RM52 5U rackmount, sized for a standard 19-inch server rack and cooled by Noctua air across the CPU and GPU stack. When a rack isn't available, EMARQUE can build the same platform into a sound-dampened pedestal chassis for a lab or office-edge placement.
  • Can I bring my own components or upgrade later?
    Yes on both. Customer-supplied components (BYO GPU is common for teams with existing NVIDIA inventory) are validated and integrated as part of EMARQUE's multi-point QA. Field upgrades are supported: every chassis EMARQUE ships has GPU, RAM, and NVMe headroom designed in, with documented part numbers so the customer's IT team can self-service additions.
  • What software ships pre-installed?
    Default Ubuntu 24.04 LTS image includes: NVIDIA driver, CUDA Toolkit, cuDNN, PyTorch with the right CUDA wheel, Ollama, vLLM, JupyterLab, Docker / Podman, NVIDIA Container Toolkit, and a benchmark suite (MLPerf-derived) used to produce the delivery report. EMARQUE can pre-install a custom stack on request.
  • What's the difference between AI PRO 500 and the EMARQUE AI Server?
    AI PRO 500 is a 5U rackmount AI server for individual researchers, small teams, and pre-production validation: up to 4× RTX PRO 6000 Blackwell Workstation Edition, 256 GB ECC, on workstation-grade Threadripper PRO silicon. The EMARQUE AI Server is a 6.5U rackmount for org-wide production: up to 8× RTX PRO 6000 Blackwell Server Edition (768 GB), up to 8 TB ECC, ConnectX-class SuperNIC networking, redundant Titanium power. Same software stack, different scale.

Build your AI PRO 500.

Open the configurator, pick your CPU, GPU mix, and storage tier. EMARQUE returns a tailored quote and a build sheet you can send to procurement.

Related searches · rackmount AI server Malaysia · Threadripper PRO AI server · NVIDIA RTX PRO 6000 Blackwell server · 4-GPU AI server · custom AI server Malaysia · deep learning server · multi-GPU rackmount server · private RAG server · fine-tuning server · 5U rackmount AI server · AI server price Malaysia

02Talk to EMARQUE

Tell us about your workload.

Model size, concurrency, latency budget, deployment site. EMARQUE returns a quote in MYR within one Malaysian business day, sized to the workload, not the salesperson’s quota.

  1. 01

    Key Account Manager

    +6012 627 2280
  2. 02

    Request for Quotation

    business@emarque.co